AI Agents Are Burning 15× More Tokens Here’s Why
This AI lecture walks through "AI Agents Are Burning 15× More Tokens Here’s Why" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.
HomeAI
Systems of intelligence
@DrIbrarAhmedAI
How modern AI works when you strip away the demos: next-token prediction, attention, embeddings, vector search, RAG, KV cache, speculative decoding, and agents with MCP. Each article pairs with the full lecture.
This AI lecture walks through "AI Agents Are Burning 15× More Tokens Here’s Why" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.
This AI lecture walks through "AI Agents Are Dangerous Without Sandboxes. Here's Why" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Vector-Only RAG Is Dying. Here's What Enterprise AI Uses Now" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Can You Spot the Deepfake? The Eye Test Already Failed" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Claude Mythos Found 10,000 Serious Flaws in Its First Month" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "GPT-6 Astra Is Different: AI Now Finishes the Job" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Kimi K3: 2.8T Parameters, But Only 104B Active Per Token" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.
This AI lecture walks through "How ChatGPT Actually Writes: Next Token Prediction Explained" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Why AI Models Think Longer Before Answering | Test-Time Compute Explained" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Speculative Decoding: Faster LLM Token Generation" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "Why LLM Prediction Is Compression (Entropy Explained)" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.

This AI lecture walks through "How AI Agents Work: Tools, Memory, MCP, Guardrails" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.
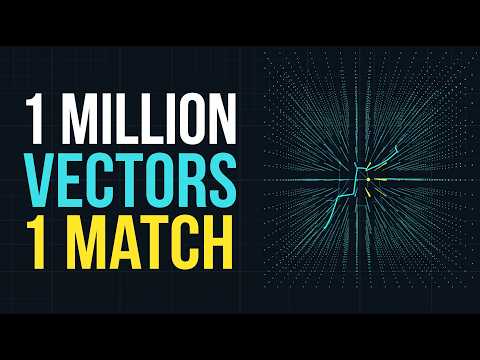
One query. A million stored vectors. Do we compare against every one? That is exact nearest neighbor, and it is correct, and it is linear. At that scale, latency is the product. A point in space is not a search. This lecture is the store those numbers live in, and the hop that finds the nearest neighbor without reading every row.

This AI lecture walks through "RAG Explained: Why LLM Guesses Without Retrieval" with the same production focus I use on the channel: what breaks, what the metrics say, and what to change.